Rendering directional shadow maps in 2026 - Part 2
We ended the last part with the following state:
We technically have shadows, but at the expense of shadow acne. Let’s fix that.
Shadow biasing
The fundamental problem
Okay, first let’s understand the problem. Why do we get this pattern? Remember our shadow map, and how it is basically a batched set of parallel rays, stored as intersection depth in a 2D texture. These ray intersection results are what we use directly to determine if a fragment on screen is occluded.
The issue lies in the fact that this 2D texture has a resolution limit. What we actually store is the intersection result of the ray that passes at the center of the given texel. But what we do is that we use this value as a comparison reference for any fragment, even those whose ray doesn’t go through the center of the texel. Because of that we get incorrect occlusion results, which leads to shadow acne.
Let’s visualize it, it might be easier to understand:
I added debug quads that project the depth map texels onto the scene. Each quad corresponds to one shadow map texel. If you look close, you can see that it is those quads that are actually casting shadows, not the scene geometry directly. (though technically the quads are just the scene geometry projected onto the 2D shadow map).
So, what was the point then? Why do we even bother with this approach if it does not provide correct occlusion results? Because it is still a great approximation which we can work around.
So how do we fix it? By accepting that we are dealing with an approximation, and that we can work around it by using a technique called shadow bias.
Constant shadow bias
So, as stated, the discrete nature of the shadow map is what leads to acne:
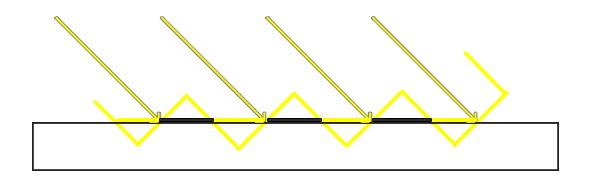
When the mesh surface is not orthogonal to the light ray, a part of the surface is likely to “slip” below the texel depth quad. But what if we add a small offset to the depth value we sample from the shadow map?
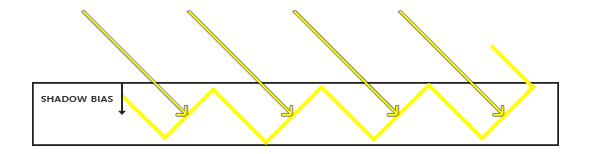
We call such an offset a shadow bias. Let’s try it out:
If you play around with the interactive demo, you’ll notice that by using a big enough bias, the acne goes away. But start cranking the bias too high, and the shadow will start to detach itself from its caster, in a phenomenon known as Peter panning (as a nod to Peter Pan’s shadow getting detached from its owner).
You have to find a middle ground between getting rid of acne, and not peter panning.
You will likely note that we don’t get a nice and easy formula for computing an optimal bias. It’s because there is none. You need to find a good value by trial and error. Historically, artists have been responsible for setting up bias values. These are often set per light in a scene for the best visuals.
If you play around some more, you may notice that changing the resolution of the shadow map impacts the effect of bias. That’s because the texel world size gets greater, and while the bias is not exactly in world units but depth units, as both are proportional to each other; the bias needs to be scaled proportionally to texel world width if you want to reuse your settings across different resolutions.
If you play around now and modify the shadow map resolution, you will notice that the bias behaviour now tends to be a lot more predictable.
You might also notice that the higher the resolution, the lower the peter panning. This is because peter panning offest scales with shadow texel size. If the resolution is higher, the texel size is smaller, and thus the peter panning shifting is smaller, and less noticeable.
Finally, you may also notice that the steeper surfaces (compared to the light direction) require a higher bias to fully get rid of acne. By the time you stop getting acne on the sphere, the shadows from other objects are already peter panning. Frustrating, right? Let’s improve that.
Slope-based bias
As you may have noticed before, the greater the relative surface slope to the light direction, the greater bias you need to apply to get rid of acne. To the point where you have no choice but to peter pan.
So let’s be smart about it. How about we use that relative slope to dynamically adjust the bias?
This method is what we call slope-based bias. While there are variants of it, this formula is probably the closest to what is considered to be the standard one.
As you can see, it drastically reduces peter panning, as we can use much lower bias factors with it.
You may note that we are using a max clamping value that provides a hard limit to the bias. This is because unclamped bias can still lead to excessive peter panning when using grazing angles:
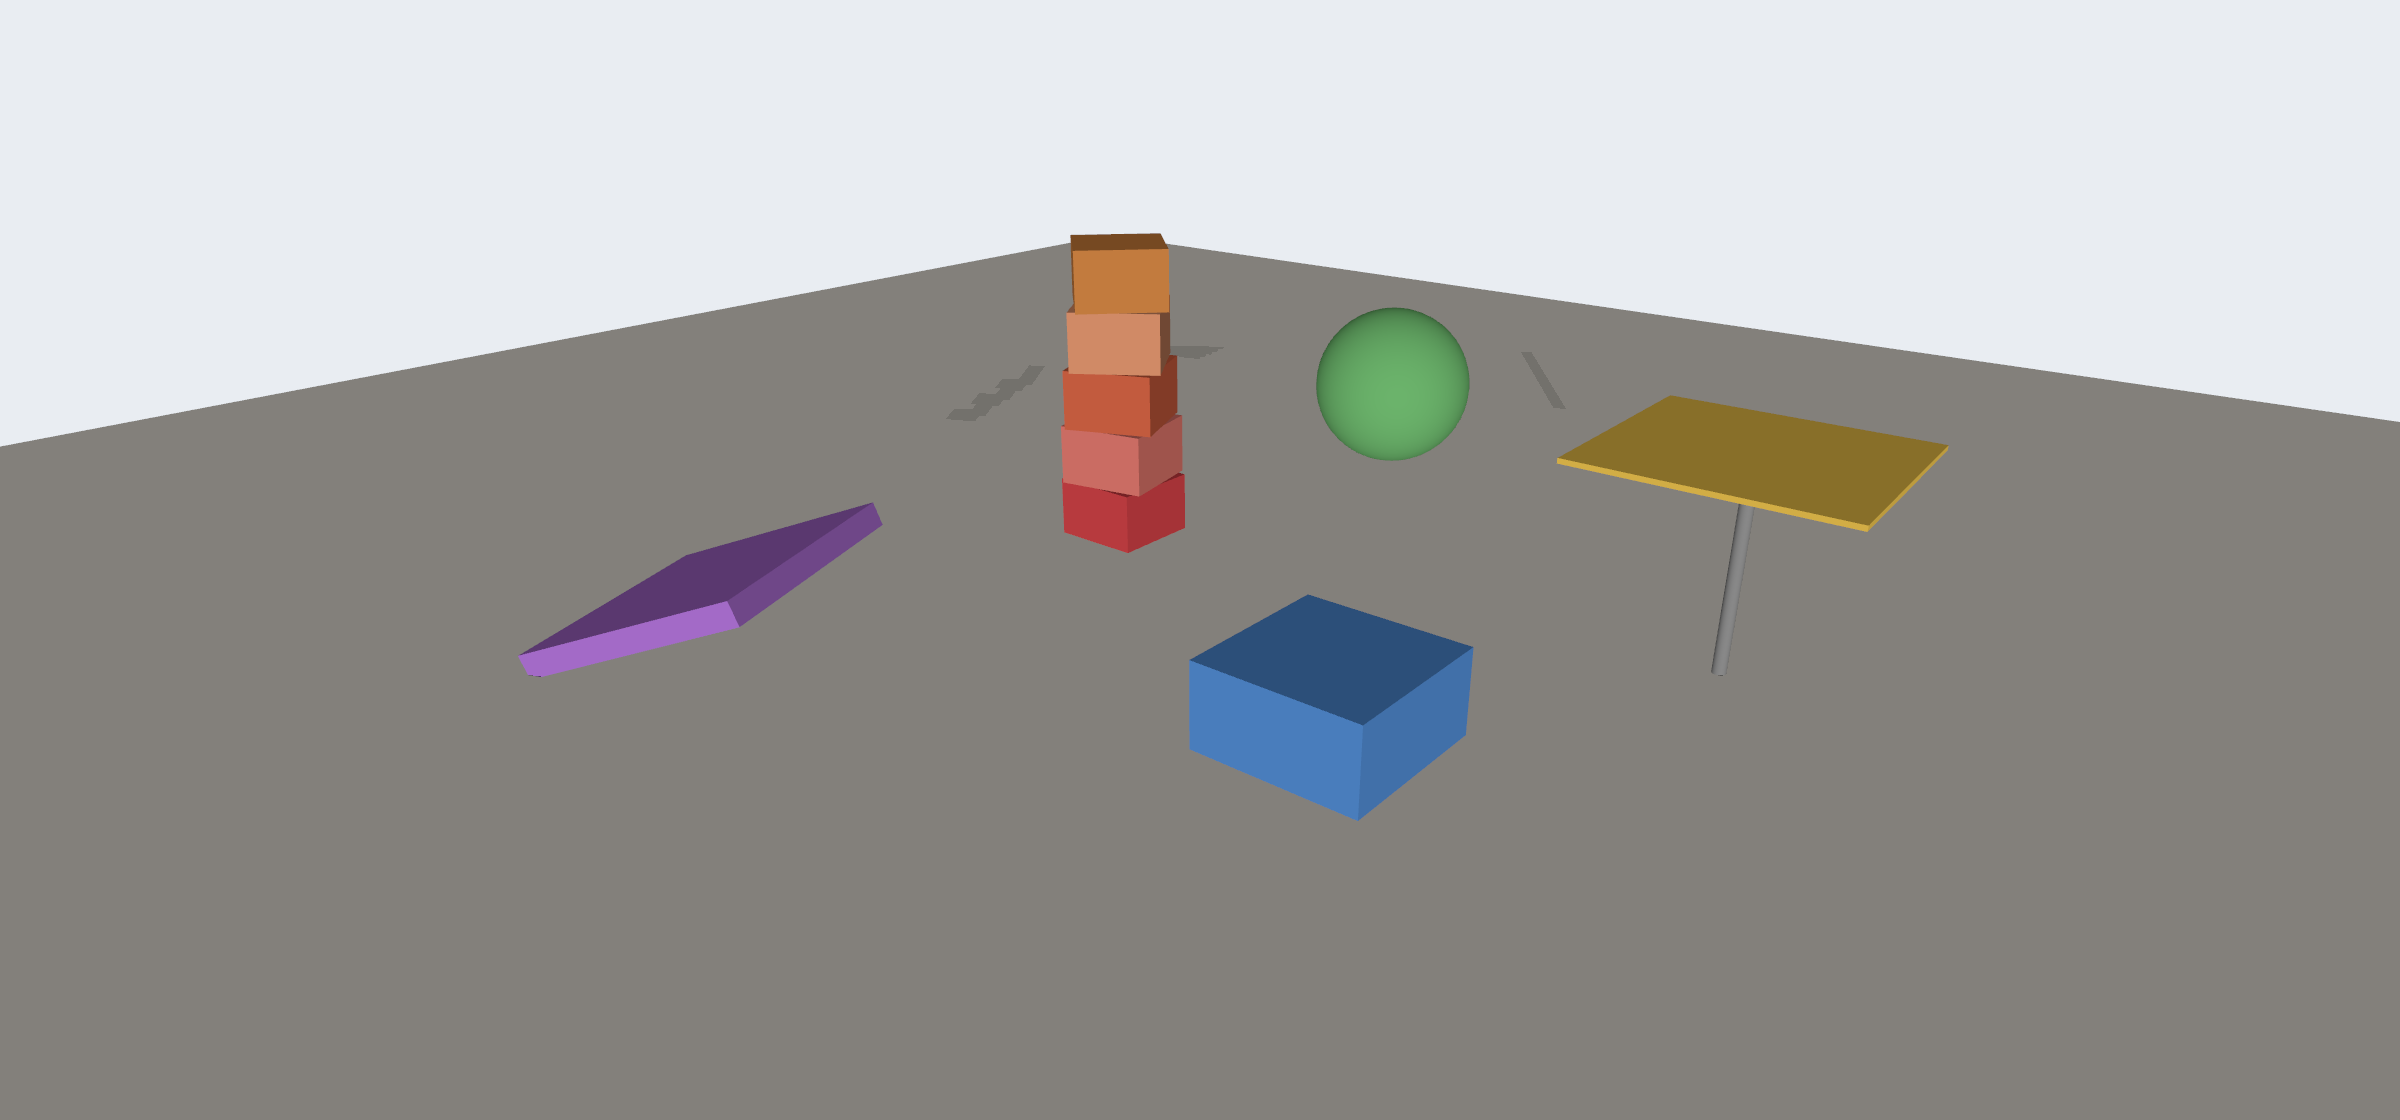
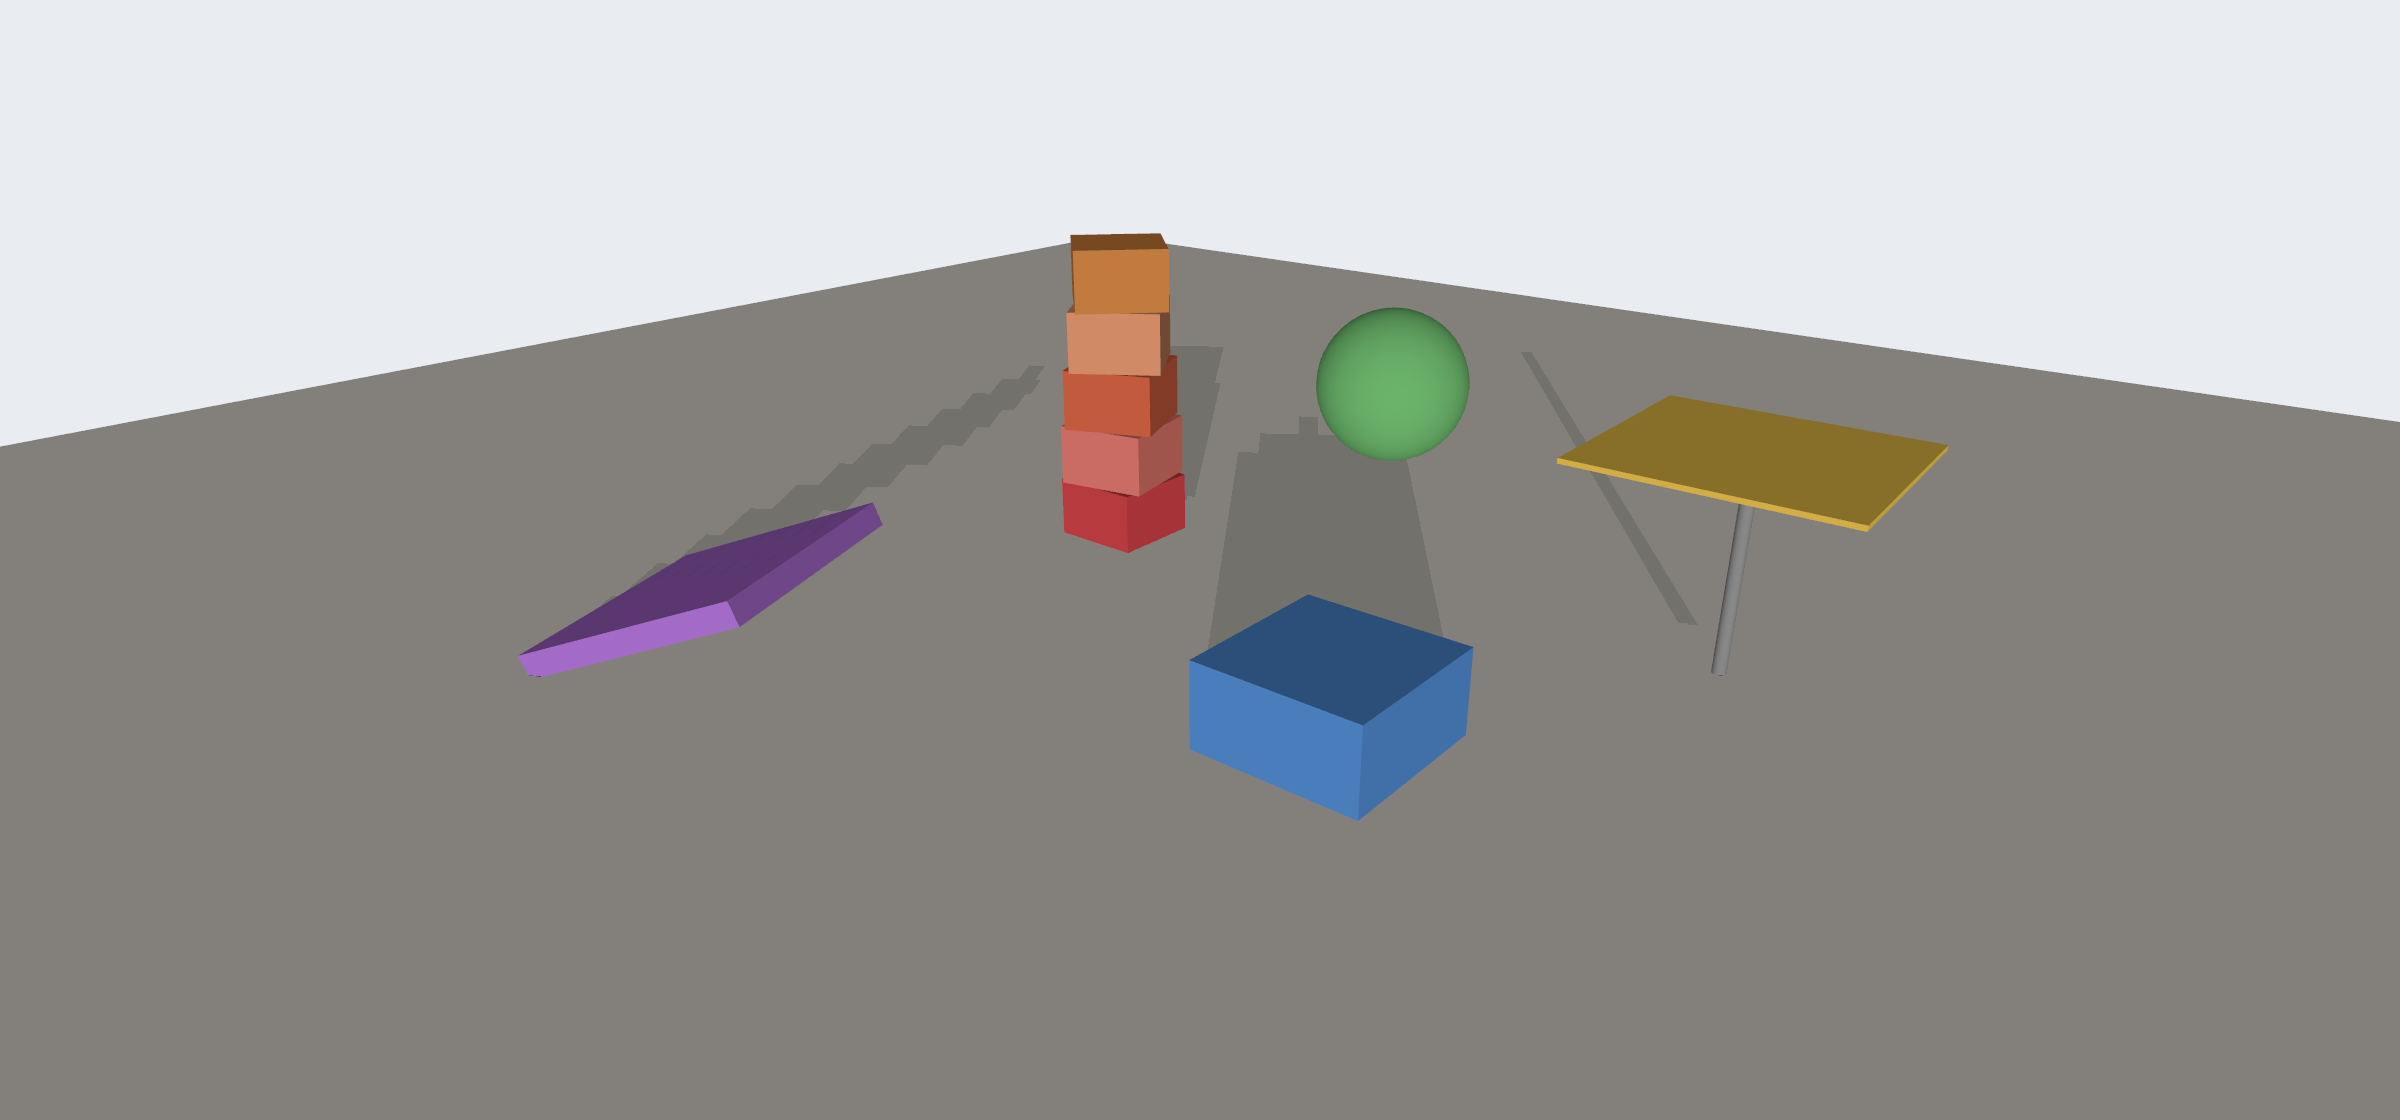 ClampedUnclamped
Do note that this tends to be an edge case, so for most cases you can keep a high-bias clamp.
Hardware bias
Slope-based bias has become such a mainstream approach to shadow biasing that it is natively supported by graphics APIs. It is often referred to as “hardware bias” because it is typically implemented directly in the hardware, which can provide better performance compared to software-based biasing.
Hardware bias is applied at the rasterizer stage, before the depth test. As such, you actually use hardware bias for the shadow pass, not the main render pass. This means that the bias is pre-applied to the shadow map, so you don’t need to apply it in the shader.
Setting up hardware bias is usually done when setting up a pipeline state object (PSO) depth stencil state, though some APIs set it as a dynamic state (like Metal and OpenGL). Thankfully, the hardware bias logic specification is universal between APIs, and I would recommend you read the WebGPU specification for more details.
The APIs take three bias parameters:
- Constant bias
- Slope scale bias
- Depth bias clamp (optional, some APIs don’t support it)
These are the same values we used in the previous demo, but with the caveat that the formula is a bit different:
bias = constantBias * r + slopeScaleBias * maxDepthSlope
maxDepthSlopeis the maximum of the horizontal and vertical slopes of the fragment’s depth value. In shader code, it would be equivalent tomax(abs(dpdx(depth)), abs(dpdy(depth))), with the nuance that, as this value is the same across all fragments of the same primitive, the fixed function has to compute it only once per triangle.ris a bit more complicated. It is what we call the smallest resolvable depth difference. Basically, it is the smallest depth delta between two distinct depths for the current primitive. For UNorm depth formats, it is1/(2^bits - 1), where bits is the number of bits in the depth format, because the minimum depth delta is the same independently of the current depth. For float formats, it is a bit more complicated, as the minimum depth delta is not constant across the primitive. In that case, it is set to2^(exp(max z)-23).- if available, the depth clamp is applied to
biasafterward, and works the same as ourmaxBiasvalue from the previous section. It should be noted that three.js does not support bias clamping, so we can’t use it in the demos.
In the demos, so far, I have used 16-bit UNorm depth formats, so I get r = 1/65535.
Do note that r only affects the constant bias, not the slope factor.
A point to note is that, as maxDepthSlope is using derivatives, it already takes the resolution into account:
using derivatives means that this value is proportional to texel size.
Also, since we use a depth differential rather than the tangent of the angle between the normal and the light direction, we are not using quite the same slope factor. In theory, it is more accurate as it is based on the actual slope of the primitive, rather than using a normal that does not correspond to the actual geometry.
Since the setup is quite different, we can’t use the same values as the previous part, so this will require another trial and error process to find the right values:
Receiver plane bias
Another approach for biasing is a method called receiver plane bias. This method relies on two observations: the further a fragment is from the shadow texel center, the more it differs from the stored depth value; and at a shadow texel granularity, the geometry surface can be approximated as a plane.
Based on these observations, the technique biases the fragment depth value by:
- first emulating the surface plane at the fragment position. Geometrically speaking, we retrieve the tangent plane.
- computing the intersection between the plane and the light ray through the shadow texel center
- using this intersection as the fragment depth instead.
Let’s illustrate this:
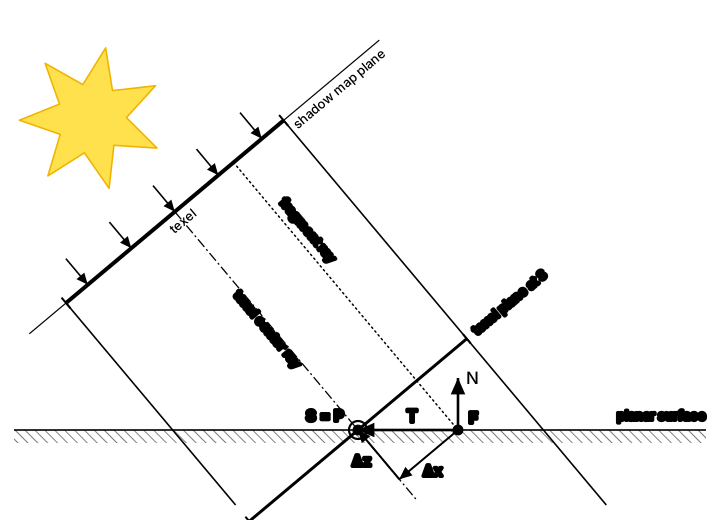
- $F$ is the fragment position.
- $\vec N$ is the surface normal at $F$.
- $\vec T$ is the tangent vector of the surface at $F$.
- $S$ is the surface point stored in the shadow map.
- $P$ is the intersection between the tangent plane and the light ray through $S$.
- $\Delta x$ is the distance between $F$ and $P$, projected onto the shadow plane.
- $\Delta z$ is the computed bias.
- $\epsilon$ is the final bias error.
With a flat surface, we get a perfect bias. That’s pretty nice. But in practice we don’t often get flat surfaces, so let’s see what we get with a curved surface. First, let’s look at a convex one:
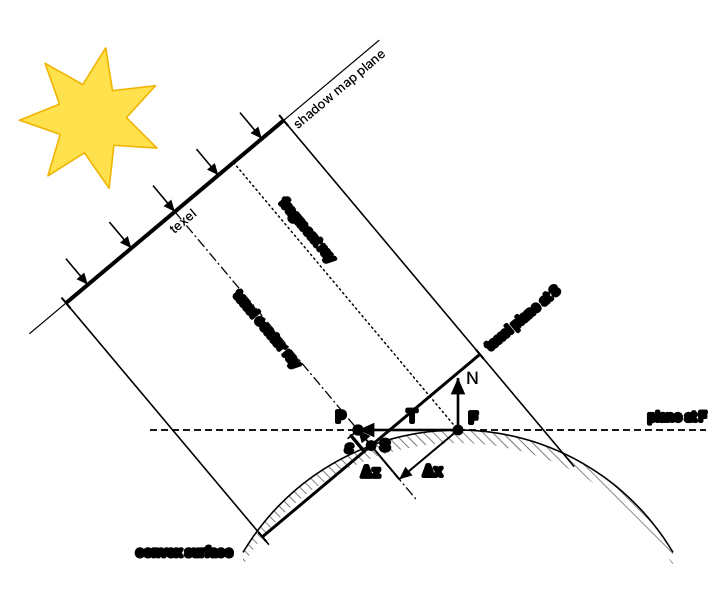
Now we can see that we get some slight over-biasing, which is not ideal, but should be acceptable. Let’s now see a concave surface:
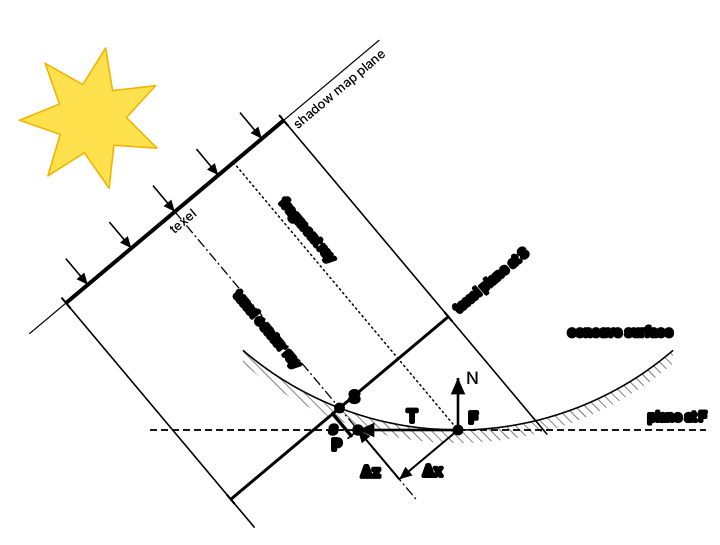
Yeah… It was predictable, but sadly it is under-biasing. But it still helps in reducing the shadow acne, and with a bit more bias we can cover for situations like this.
Now let’s see how we implement it shader-wise. There are two approaches to achieve it: using screen-space derivatives or manually calculating the tangent plane.
Using screen-space derivatives
This is the original approach, as presented by John Isidoro back in 2006 at GDC.
Basically, we want to retrieve
where $b$ is the receiver plane bias, $\overrightarrow{CS}$ is the UV-space vector from the texel center to the fragment shadow coordinates, and $\frac{\partial z}{\partial UV}$ is the partial derivative of the depth value in the UV-space.
$\overrightarrow{CS}$ is the easy part, as we can easily retrieve it from the shadow coords and the shadow map resolution:
let distanceToCenterUv = (fract(shadowCoord.xy * shadowResolution) - 0.5) / shadowResolution;
The partial derivative is a bit more tricky. With screen-space derivatives, we can get $\frac{\partial z}{\partial XY}$, $\frac {\partial U} {\partial XY}$ and $\frac {\partial V} {\partial XY}$:
let dz_dXY = vec2<f32>(dpdx(shadowCoord.z), dpdy(shadowCoord.z));
let dU_dXY = vec2<f32>(dpdx(shadowCoord.x), dpdy(shadowCoord.x));
let dV_dXY = vec2<f32>(dpdx(shadowCoord.y), dpdy(shadowCoord.y));
but that’s not exactly what we need, which is $\frac{\partial z}{\partial UV}$.
Thankfully, as explained in Isidoro’s presentation, we have a great mathematical tool to help us out: the Jacobian.
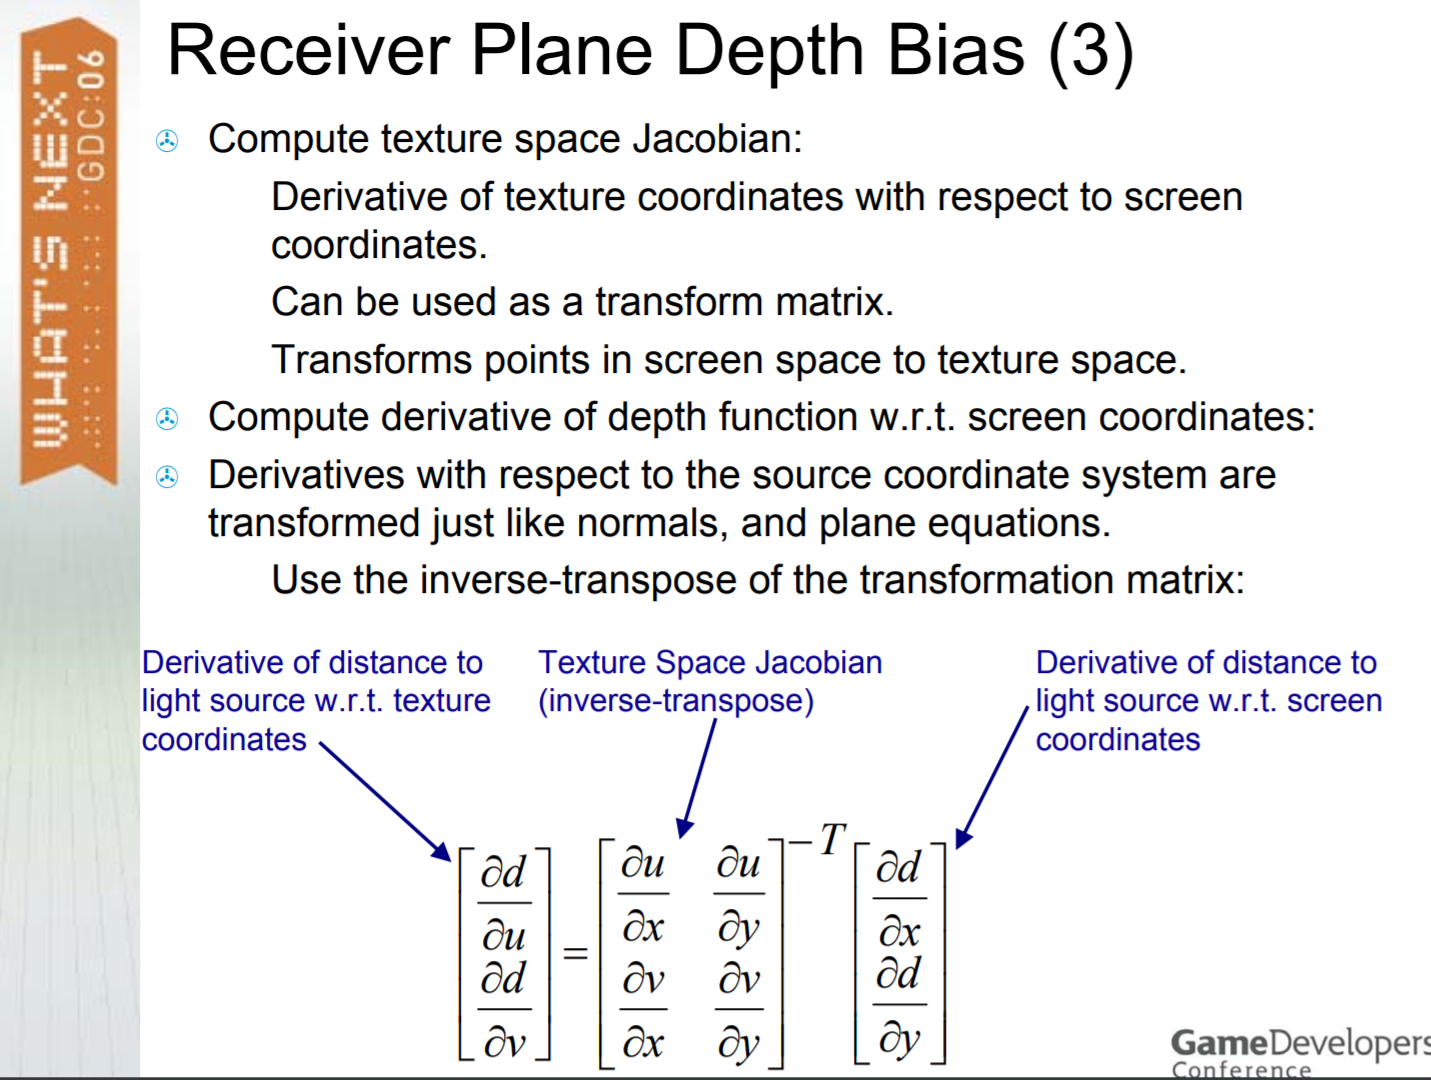
(do note that the slide uses $d$ instead of $z$ like we do)
Let’s develop that inverse transpose:
That determinant can be zero, which happens only when the plane normal is perpendicular to the light direction. Usually, that means that $N \cdot L = 0$, so for most cases we can ignore bias.
In shader code, this is translated to:
let det = dU_dXY.x * dV_dXY.y - dU_dXY.y * dV_dXY.x;

var dz_dUV = vec2<f32>(0.0, 0.0);
if (det != 0.0) {
    dz_dUV.x = dot(dz_dXY, vec2<f32>(dV_dXY.y, -dV_dXY.x)) / det;
    dz_dUV.y = dot(dz_dXY, vec2<f32>(-dU_dXY.y, dU_dXY.x)) / det;
}
We can then complete the formula:
let bias = dot(dz_dUV, distanceToCenterUv);
Let’s try it:
You will notice that we’ve also added a bit of additional constant bias. If you set it to zero, you will see that the receiver plane bias by itself is not enough. This is due to both depth quantization and concave surfaces. As such, a bit of additional bias is required.
If you look close, you will also notice that the concave parts of the scene (like where boxes meet the surface plane) still have some self-shadowing artifacts, as we predicted earlier.
Overall, though, it provides a pretty good result with less tweaking required, and can be combined with other techniques to provide ideal results.
Using a normal vector
When you don’t have reliable access to primitive-level derivatives, you can still use the same principles using a provided normal vector. On average, the closer the normal vector is to the actual geometric normal, the better. Interpolated normals are more approximative, but usually still okay. Normal-mapped normals are where things tend to break a bit, so expect some artifacts.
The trick here is to project that normal into the light space, so that we can reuse the same logic as in the derivatives subsection.
let dz_dUV = -shadowNormal.xy / shadowNormal.z;
The question then becomes: How do we retrieve that normal vector in the first place? Since the light projection is an orthographic matrix, we can directly use the transpose inverse of the light-space matrix (combined with the NDC-to-UV transform matrix) as a normal matrix and apply it directly.
If, instead, you use the light view-projection matrix (and manually apply the ndc-to-uv transform), then do not forget
to apply a (2, -2, 1) scale to the “shadow normal” after applying the normal matrix to it.
I used this opportunity to also apply slope-based bias to show off how all techniques can be combined.
If you don’t have the possibility of providing the light normal matrix, there is an alternative approach using the tangent and bitangent vectors. You can even generate some on the fly if need be:
let v = select(vec3<f32>(0.0, 1.0, 0.0), vec3<f32>(1.0, 0.0, 0.0), abs(normal.y) > 0.99);
let tangent = normalize(cross(normal, v));
let bitangent = cross(normal, tangent);
You can use their projection into shadow space to compute $\frac {\partial z} {\partial UV}$:
// Where one world unit along each tangent lands in shadowCoord space
// (we assume that the ndc-to-uv transform is included in `lightMatrix`)
let d1 = (lightMatrix * vec4<f32>(worldPos + tangent, 1.0)).xyz - shadowCoord;
let d2 = (lightMatrix * vec4<f32>(worldPos + bitangent, 1.0)).xyz - shadowCoord;

// dz = g.x * du + g.y * dv holds for both tangents, so solve for g = dz/d(u,v)
let det = d1.x * d2.y - d1.y * d2.x;
var dz_dUV = vec2<f32>(0.0);
if (abs(det) > 1e-8) {
    dz_dUV = vec2<f32>(
        d1.z * d2.y - d1.y * d2.z,
        d1.x * d2.z - d1.z * d2.x
    ) / det;
}
While it allows you to avoid having to produce and fetch a normal matrix, it is achieved at the cost of an additional matrix multiplication.
Normal offset bias
The final bias technique we will cover is called normal offset bias. It consists in offsetting the original world position along its normal before projecting into light-space. Only the lookup position moves, the shadow map itself is unchanged: it is as if we were testing against a slightly inflated version of the receiver. The goal is to move the tested position out of the “hazard zone”, the thin region around a surface where the shadow map texels can still hold depths from that very surface, which is what causes self-shadowing.
At grazing angles, this offset allows us to shift the bias horizontally rather than simply depth-wise, making this approach particularly useful for reducing self-shadowing artifacts.
For a deep dive, I highly recommend Daniel Holbert’s GDC poster “Saying goodbye to shadow acne” which explains the
technique in detail.
Let’s implement it in our example. We will modify the light-local position retrieval function, but we will keep the basic shadow visibility function with no extra bias.
That’s impressive. With just a little bit of tweaking, we have almost no acne, with little to no peter panning.
But the result is not perfect: if you look closely, you can still see some self-shadowing in concave transitions, and raising the normal offset does not reliably remove it. That’s because, near a concave corner, the offset is computed from the fragment’s own normal only. It can push the fragment out of its own surface’s hazard zone while landing it inside the hazard zone of the neighbouring surface, which has a different orientation.
Not all concave surfaces get this issue, but as soon as we have somewhat tight concave spaces like we have in the scene, you will get self-shadowing. In these cases, normal offsetting alone is not enough, and if you truly want to solve it, you will need some additional biasing.
Another side effect of this technique is that it actually “shrinks” shadow silhouettes. You can visually see this by cranking up the normal offset bias.
Back face shadow maps, a.k.a. side-stepping the issue entirely
Lastly, another technique I wanted to cover is back-face shadow maps. While not exactly a bias technique, it has emerged as a widespread technique for dealing with self-shadowing artifacts.
The principle is quite simple: instead of rendering front faces for shadow maps, we render back faces (i.e., we cull front faces). The goal with it is to keep receiving useful occlusion information while reducing self-shadowing occurrences. Since fragments on these back faces tend to face away from the light anyway, they would be unlit due to $\vec L \cdot \vec N < 0$, so even if there were self-shadowing artifacts, they would not be visible.
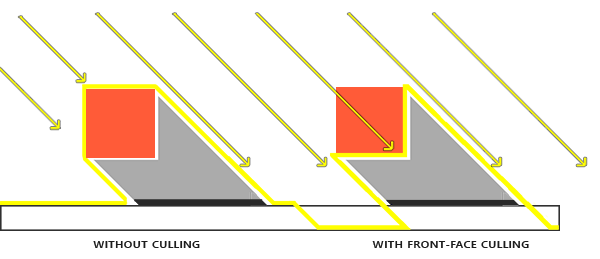
Let’s try it out:
Even without any bias, we get some pretty good results, but a close look will still reveal some self-shadowing artifacts.
If you look at the box borders that go from lighted to unlighted, you can easily see some self-shadowing staircase artifacts. Looking some more, at the junction between boxes and the surface plane, you can also find some light leaking, the result of a slight peter panning.
If you lower the shadow map resolution, not only will these artifacts be more visible, but at some point, the thin “umbrella” solid will start to self-shadow as well.
If a mesh is too thin (relative to the shadow map resolution), it will self-shadow.
A touch of normal offset bias should fix the self-shadowing issue. For the peter panning, let’s try to add a bit of negative slope-scaled bias as well:
Okay, the normal offset bias has fixed the self-shadowing issue. However, regarding the peter panning, the slope-scaled bias can’t fix the issue without creating some self-shadowing.
Also of note, we are working with closed-surface meshes here, but non-closed-surface meshes need additional care.
Conclusion
Biasing is a technique used to fix self-shadowing issues, resulting in acne in worst cases. There is no final out-of-the-box solution for biasing, just a collection of techniques that can be used to mitigate the issue.
Usually, modern engines tend to use a combination of these techniques to achieve the best possible results. For instance, I have worked on an internal engine that combines hardware bias and receiver plane bias.
To implement shadow mapping in your own engine, you will need to look at those techniques and choose one for yourself. From my personal experience, I have found that normal offset biasing is the best to start with, but it might not fit your own requirements.
It should be noted that some of the self-shadowing issues can be further alleviated using suitable shadow filtering, but this is a topic we will be covering in the next part.
Previous part: Part 1. Next part: Part 3.
References
- LearnOpenGL - Shadow mapping
- Render Diagrams - Shadowmap Bias
- WebGPU specification - Depth stencil state
- Microsoft Docs - Depth Bias
- Real-Time Rendering, 4th Edition - 7.4. Shadow maps
- Shadow mapping tricks and techniques, John Isidoro, GDC 2006.
- Shadow normal offset bias, Godot proposals